

Your p99 Is Lying to You: Percentiles Don't Compose
Ten services at p99 don't make a p99 page load: why per-service percentiles mislead, why averaging them is meaningless, and what the client sees that you don't.
5 min read
On this page
Every service in your company has a p99 latency panel, and most of them are green. Users are still telling you the app feels slow. Both things are true at the same time, and the reason is arithmetic rather than instrumentation.
One page, ten services
Say a page load fans out to ten backend services. Every one of them is meeting its p99 target: ninety-nine requests in a hundred come back inside the threshold, one does not.
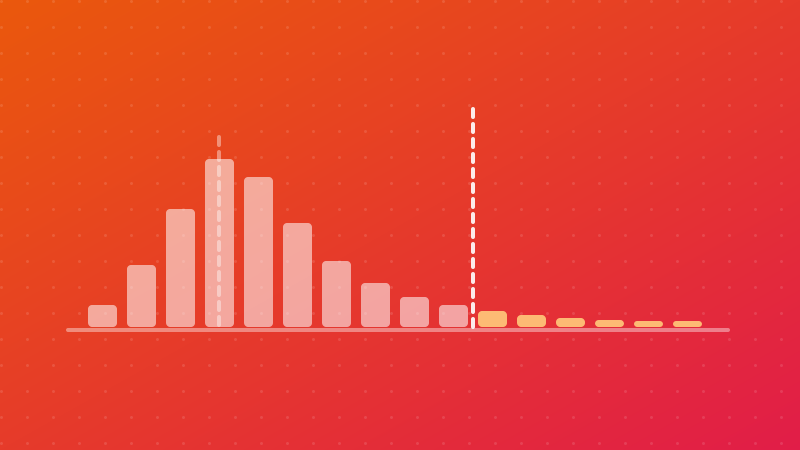
What fraction of page loads are entirely inside the threshold? If the calls are roughly independent, it is 0.99 to the tenth power — about 0.904. So very nearly one page load in ten contains at least one slow call. Every service is at p99. The page is at p90.
Turn it around and it gets worse. For the page to hit p99 across ten independent calls you need each service to satisfy (1 − p)^10 = 0.99, which puts 1 − p at about 0.99^0.1 ≈ 0.9990. Each service has to miss less than once in a thousand. To deliver a p99 page over ten hops, every hop needs p99.9.
That is the number nobody budgets for, and it is why adding one more service to the critical path is never as cheap as it looks. You have not added ten per cent more work. You have moved the end-to-end tail.
The shape of the fan-out decides how that surfaces. Call the ten in parallel and the page waits for the slowest of them, so the tail is the page latency. Chain them sequentially and the durations add instead, which spreads the pain but drags the median up with it. Either way, the per-service panel is measuring something other than what the user waited for.
Independence is doing some work in that calculation, and in a real system it rarely holds cleanly. Shared infrastructure correlates the tails: a garbage collection pause, a saturated network link, a noisy neighbour on the same host, a database everyone reads from. Correlation cuts both ways — the slow calls tend to clump into the same unlucky requests, which makes fewer page loads bad but makes the bad ones much worse. The independent case is the optimistic one, and it is already worse than your dashboard suggests.
Averaging percentiles across instances
The second failure is quieter, because it looks like ordinary aggregation.
You run twenty instances. Each exports its own p99. The dashboard shows the mean of those twenty numbers. That figure describes nothing at all.
Make it concrete. Instance A serves 990 requests, all at 10 ms. Instance B serves 10 requests, all at 900 ms — it is the one with the failing disk. A's p99 is 10 ms, B's is 900 ms, and the mean of the two is 455 ms. No request in the system took anything close to 455 ms. Meanwhile the true fleet p99 over all 1,000 requests is 900 ms, because the slowest ten requests are exactly the worst one per cent.
Weighting by request count does not rescue it either: that gives you roughly 19 ms, wrong in the opposite direction and far more reassuring. Percentiles are order statistics, not means, and there is no arithmetic that recovers a quantile of a union from the quantiles of its parts.
The only correct move is to merge the distributions and take the quantile once — export histogram buckets, sum the buckets across instances, then read the percentile off the total. If your metrics pipeline stores pre-computed per-instance quantiles instead of buckets, every fleet-wide latency number downstream is unrecoverable. That is one pipeline decision, usually made in an afternoon, invalidating a wall of dashboards for years.
The requests that aren't in your histogram
The third problem is the one that catches teams mid-incident. Your server-side percentile is computed over requests your server finished.
Requests that timed out at the client, that the load balancer shed, that sat in the kernel accept queue while your process was busy, that never got a connection out of the pool — none of them are in the sample. As a system degrades, the slowest work is increasingly the work that gets dropped, so the surviving sample gets faster. Your p99 can improve while the outage is in progress. It is survivorship bias with a graph attached, and it is remarkably persuasive at three in the morning.
The client, meanwhile, is measuring the other half of the request: DNS, connection setup, TLS, a radio waking up, six requests queued behind a browser's per-host connection limit, then rendering. Your timer starts when the first byte of the request is parsed and stops when the last byte of the response goes to the socket. Everything on either side of that window belongs to the user's experience and to nobody's dashboard.
What to do instead
Measure end to end, from the client, on something a person actually waited for — page rendered, tap to content, order confirmed. That is the only latency number with a human attached to it, and it is the one you should be alerting on.
Then demote per-service percentiles to what they are good for: a budget rather than a report card. Pick the end-to-end target, count the hops on the critical path, and divide backwards to find what each hop is allowed to spend. Done honestly, that exercise usually points at a different fix than the one you expected — not making the tenth service faster, but getting it off the critical path entirely.
And put your timeout and drop counts on the same panel as your latency. A percentile with no rejection rate beside it is free to improve for the worst possible reason.