

Premature Sharding: The Decision You Cannot Take Back
Sharding usually arrives years early and charges rent forever in lost joins, transactions and simplicity. What to exhaust first, and the signals that it's time.
6 min read
On this page
Somewhere in most grown-up codebases there is a function that turns an identifier into a shard number. Every query in the system has to route through it. Every new feature has to be expressible in terms of it. It was written on an afternoon three years ago, when the largest table had a few million rows, and nobody has been able to remove it since.
Sharding is one of the very few architectural decisions that behaves like a mortgage. You take it out once and you pay it every month afterwards, whether or not you're still living in the house.
The case for doing it early
The argument for early sharding is genuinely reasonable, and it goes like this.
Retrofitting a shard key onto a live system is horrible. You have to backfill, dual-write, verify, and cut over while traffic is flowing, and the window in which the two representations disagree is a source of bugs that are extremely hard to reason about. Doing it under pressure — because you're already falling over — is the worst possible time, since you have no headroom and no patience. Designing the key up front costs almost nothing when the schema is small, so surely you do it while it's cheap.
Every part of that is true. It is, in fact, much easier to choose a partition key on day one than on day one thousand. The conclusion still doesn't follow, for a reason the argument leaves out.
What you buy on day one is a key, not a schema
The shard key you choose early describes the product you have now. Sharding by user works beautifully until the product grows a team concept and every meaningful query spans users. Sharding by tenant works until one tenant is larger than the rest of the estate combined. Sharding by time works until the access pattern stops being recent-first.
A wrong shard key is considerably worse than no shard key, because it's the one thing you can't index your way out of. You've committed to a distribution before you know how the data will be read.
Meanwhile the tax starts immediately, and it's charged against every feature you build afterwards:
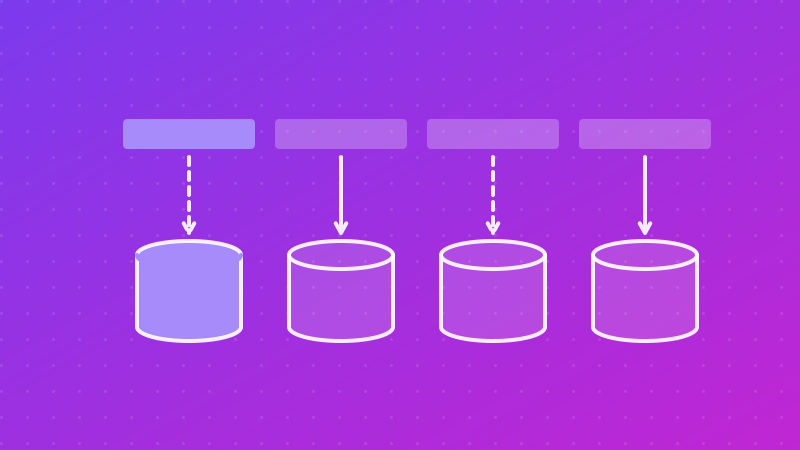
- Joins across shards stop existing. They become application-level fan-out, which means N queries, ordering done in memory, and a latency equal to your slowest shard rather than your average one.
- Transactions stop existing. A multi-entity write that used to be one statement becomes a saga with compensating actions, or a two-phase commit with a coordinator you now have to keep available.
- Global constraints stop existing. Uniqueness across all users, a global sequence, a count — each needs its own mechanism.
- Aggregate queries get slow and then get cached, and now you have a consistency problem you didn't have.
- Operations multiply. Schema migrations run N times and can fail on shard seven. Backups and restores are per shard, and a point-in-time restore of one shard leaves you with an estate that disagrees with itself.
- Every engineer must learn the key. It's the first thing a new joiner has to internalise and the source of most of their early mistakes.
Those costs don't scale with your traffic. They're fixed, and you start paying them the day you ship, which is often several years before the benefit arrives.
Exhaust these first
In rough order of cost to try, cheapest first.
Read the query plan. A surprising proportion of "we've outgrown the database" turns out to be one sequential scan on a table that acquired a filter nobody added an index for. Look before theorising.
Fix the query shape. The N+1 in a hot loop, the unbounded SELECT that pulls a whole table into the application, the endpoint that does eleven round trips where one would do. This is usually the single largest available win and it costs a day.
Buy a bigger instance. Unglamorous, immediate, and reversible. A single modern database instance holds an amount of memory and IOPS that would have been a respectable cluster not long ago. Vertical scaling has a ceiling, but you should be near it before you take on distribution, and most teams considering sharding are nowhere near it.
Add read replicas. If reads dominate, this moves the load with no schema change at all. Be honest about the limitation: replicas do nothing for write throughput, and they introduce replication lag, which is a consistency conversation rather than a capacity one.
Cache the hot path. Only after you've measured skew — if reads are spread evenly across a huge key space, a cache won't help and you'll have added a hop.
Get cold rows out of the hot table. Most tables have a long tail nobody reads: closed orders, expired sessions, old events. Archiving them, or using native table partitioning inside a single instance, shrinks the working set so it fits memory again. This gets you a large share of sharding's benefit with none of its distribution cost, and you can undo it.
Split one table out functionally. If one enormous table — events, audit logs, telemetry — dominates the volume and has a completely different access pattern, move it to its own store. Functional decomposition before horizontal partitioning, because it preserves transactions for everything that's left.
The signals that actually mean it's time
These are the ones that don't have a cheaper answer.
Write throughput is saturating a single primary. Not reads — reads have replicas. If sustained write volume is the constraint and you've already batched what can be batched, there is no vertical answer indefinitely.
The working set no longer fits in memory after you've fixed the indexes and archived the cold rows. You're IO bound on data that is genuinely all hot.
You're at or near the largest instance available, with headroom measured in months rather than years. The trend line matters more than the current number: growth that is proportional to a business metric still going up is a real forecast.
Maintenance windows no longer fit. Vacuum, compaction, index rebuilds, backup and restore all take time proportional to size. When a restore would take longer than your recovery objective allows, the size itself has become the outage risk.
Data residency. Sometimes rows have to live in a particular jurisdiction. This is a perfectly good reason to partition that has nothing to do with performance, and it's often the most defensible one.
What to do instead, today
Write down the shard key you would choose, the query it would make expensive, and the metric whose value would trigger the work. Put it in the same document as the schema. Then don't implement it.
You get most of the benefit of early planning — an argued key, a known trigger, no panic when the day comes — without paying rent on a distributed system you don't yet need. And if the metric never crosses the line, you will have been right not to.
If you want to see the shape of the cost before committing to it, the cheapest way is to model it: put a fan-out read across several partitions next to the single-instance version and watch what happens to tail latency when one partition is slower than the others. The average barely moves. The p99 tells the real story, and it's the number your users experience.